What did we test?
What did we learn?

Grex runs AI assignments across computers and keeps their results and review evidence. Here we document experiments on how that work gets done: the hypothesis, the setup, the result and the decision it changed.

Each record includes a method diagram, a short companion video and a downloadable result summary. Unfavorable results belong here too.

The experiment record

13 records · 11 themes

Showing 13 records across all themes. A record may cover more than one theme.

Read the experiment · Watch the explanation

AutomationBench · Diagnostic rerun

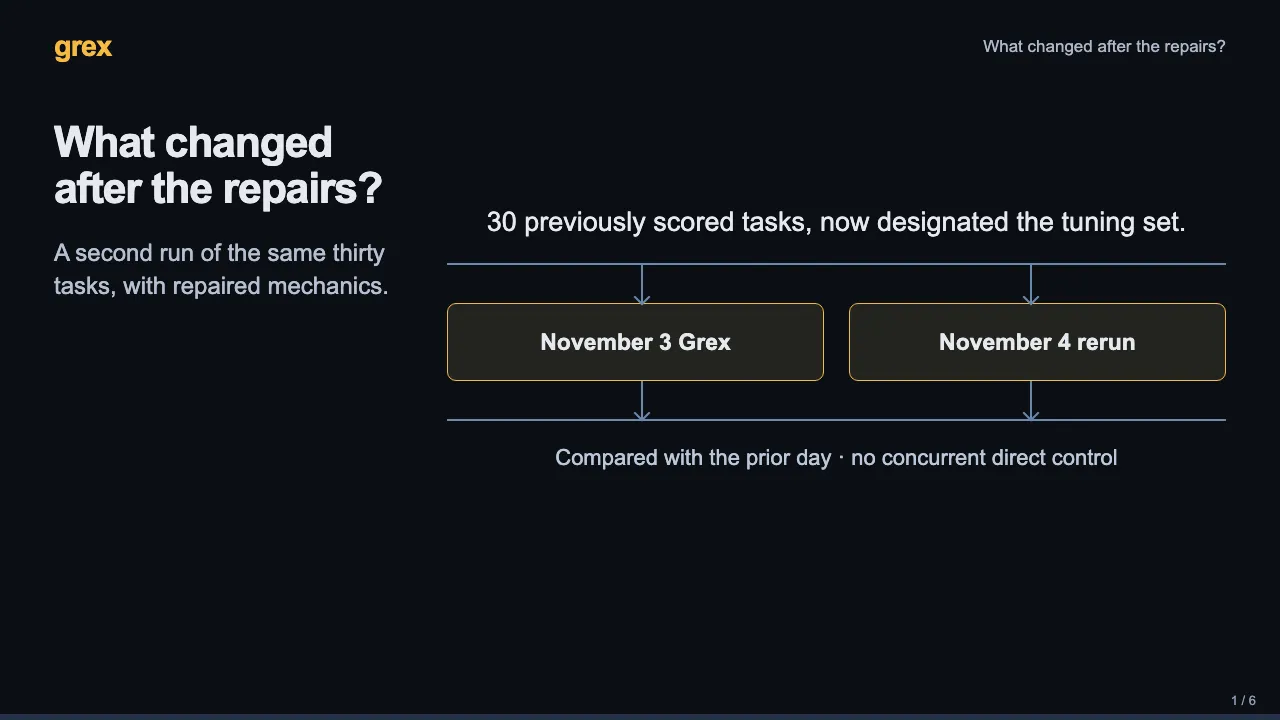
What changed after the repairs?

Grex completed 8 of 30 tasks strictly correctly, on time and without assistance, compared with 13 in the previous day's pilot. Duplicate simulated effects fell from 34 to 15 and token-bound breaches fell to zero. Correctness did not improve, and no correction rescued a failed task.

Grex 2.0

Completed · study closed
Read the experiment · Watch the explanation

AutomationBench · Matched comparison

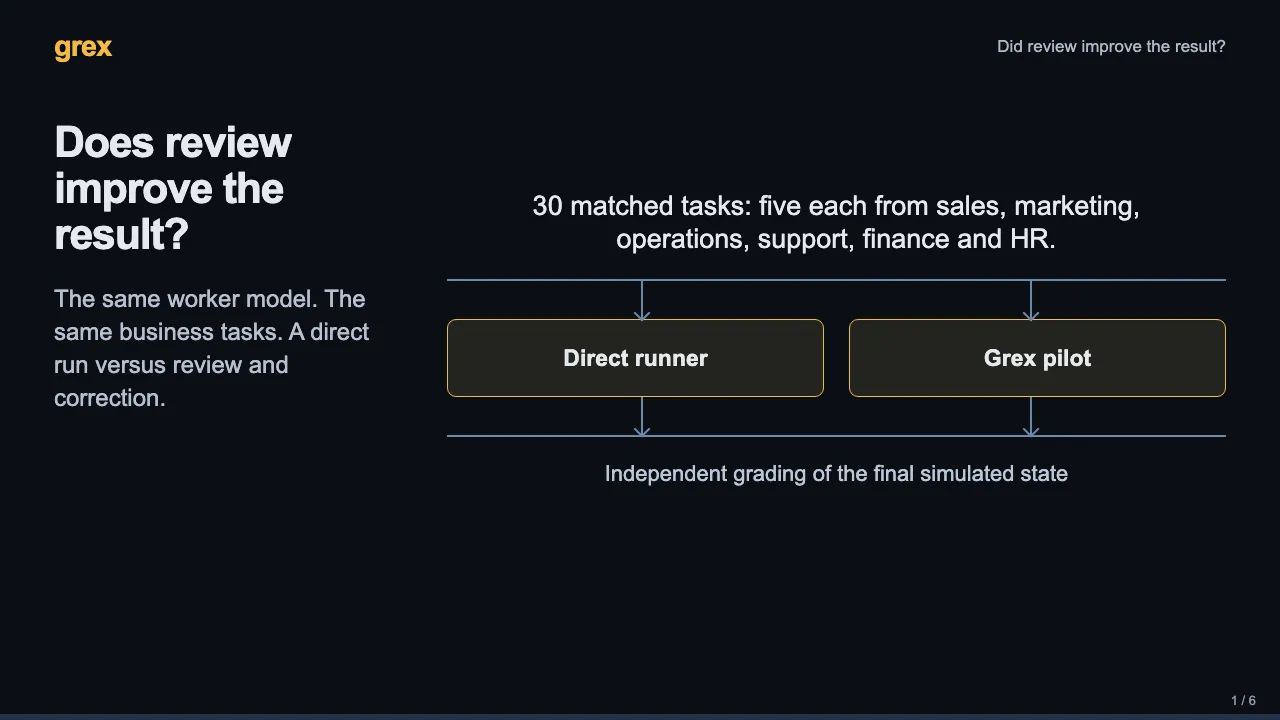
Did review improve the result?

Both arms finished 13 of 30 tasks strictly correctly, on time and without assistance. Grex took about 2.1 times the total elapsed time. The later audit found that corrections never received reviewer feedback, so this pilot cannot establish whether a functioning review-and-correction loop helps.

Grex 2.0

Completed · diagnostic evidence

Read the experiment · Watch the explanation

Website operations · Longitudinal site-monitoring study

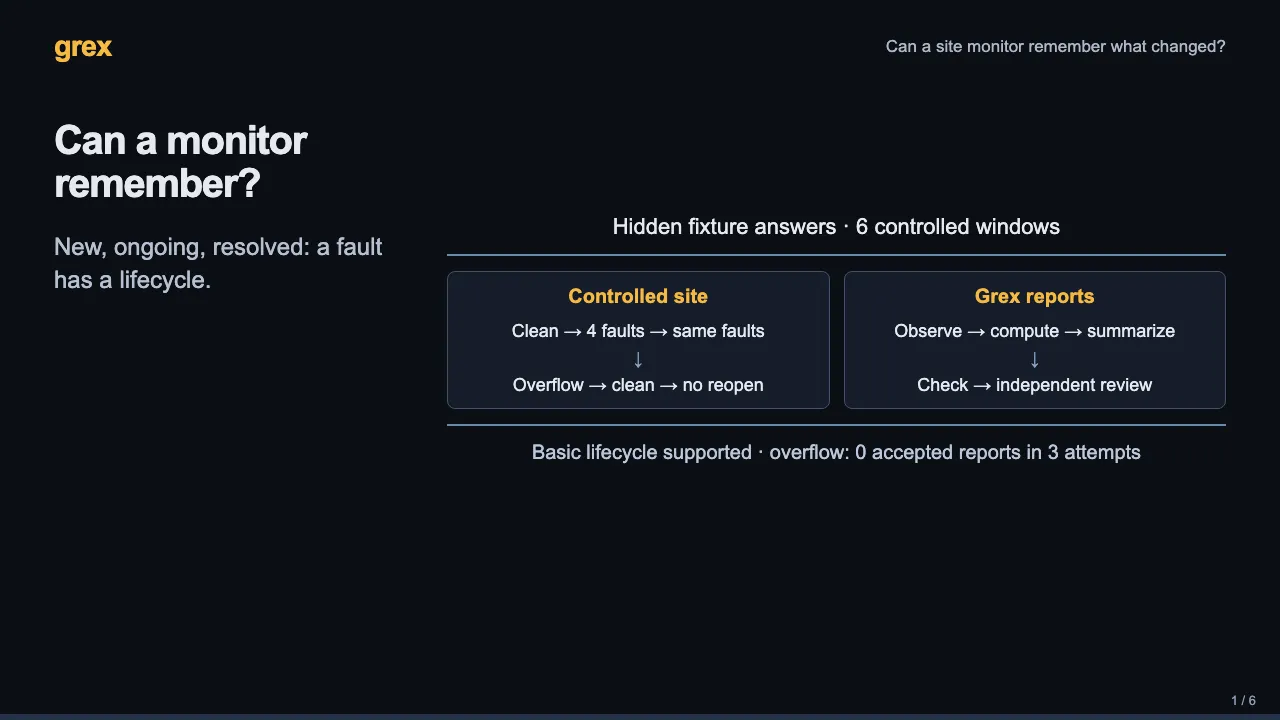
Can a site monitor remember what changed?

The controlled site correctly reported four new faults, retained their identities and later reported their resolution. But the overflow stage produced no accepted report in three attempts, so the controlled proof failed. All three production windows were eventually accepted; only two arrived within the planned two-hour window.

Grex 2.0 · October–November 2026

Closed · controlled proof failed

Read the experiment · Watch the explanation

Customer journey quality · Assisted discovery and repair study

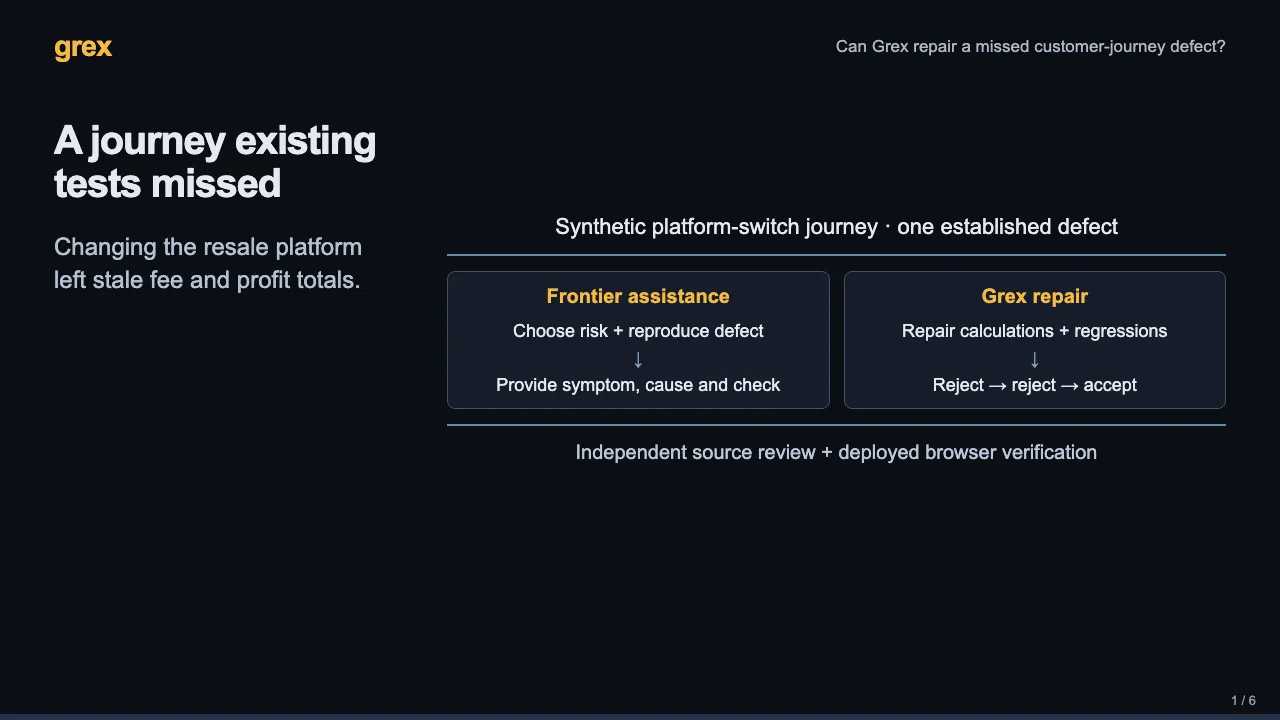
Can Grex repair a missed customer-journey defect?

Changing the resale platform left item and batch profit based on the old platform’s fee. Grex produced a two-line product repair and six focused regressions across three executions. Independent checks confirmed the released behavior. This is one assisted, verified repair, not proof of autonomous discovery or an entirely green application test suite.

Grex 2.0 · October–November 2026

Completed · one repair verified

Read the experiment · Watch the explanation

Document extraction · Context-policy comparison

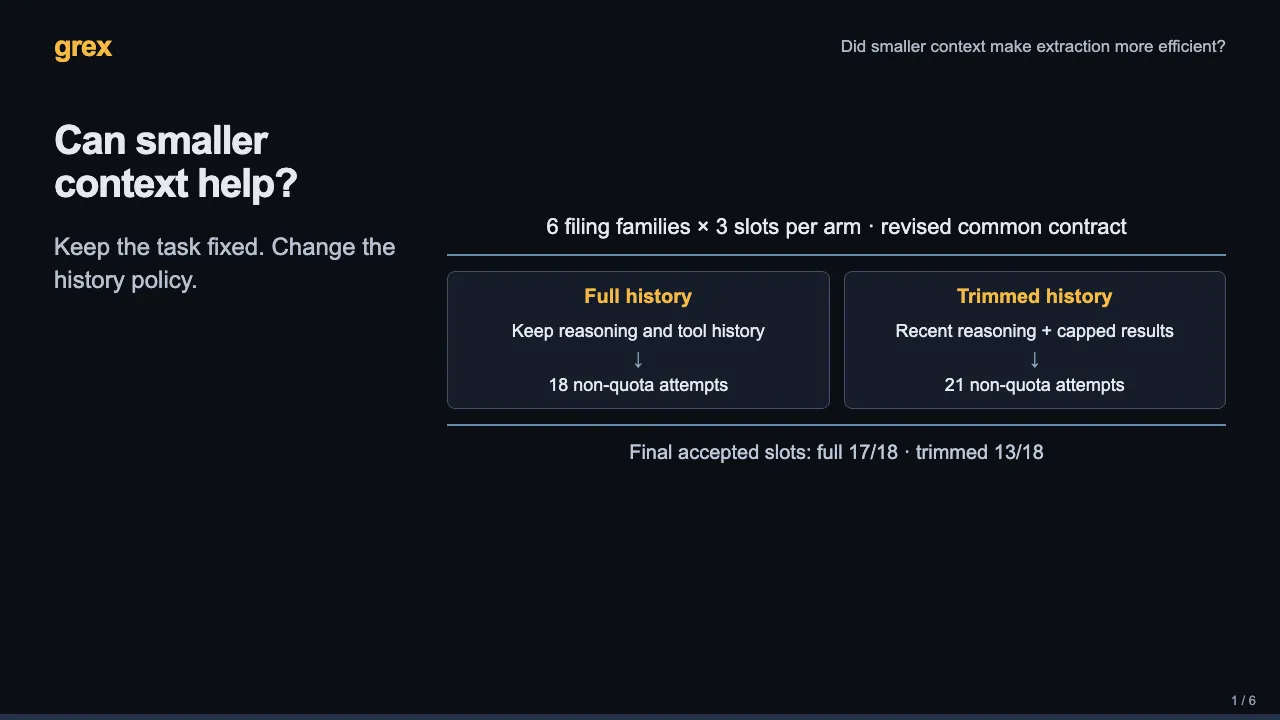
Did smaller context make extraction more efficient?

Across six filing families and three slots per arm, full history produced 17 accepted slots out of 18; trimmed history produced 13 out of 18. The trimmed arm accumulated six deadline-exhausted attempts and two outputs with critical regressions. The policy was not adopted as the default.

Grex 2.0 · October–November 2026

Completed · policy not adopted

Read the experiment · Watch the explanation

Document extraction · Document extraction study

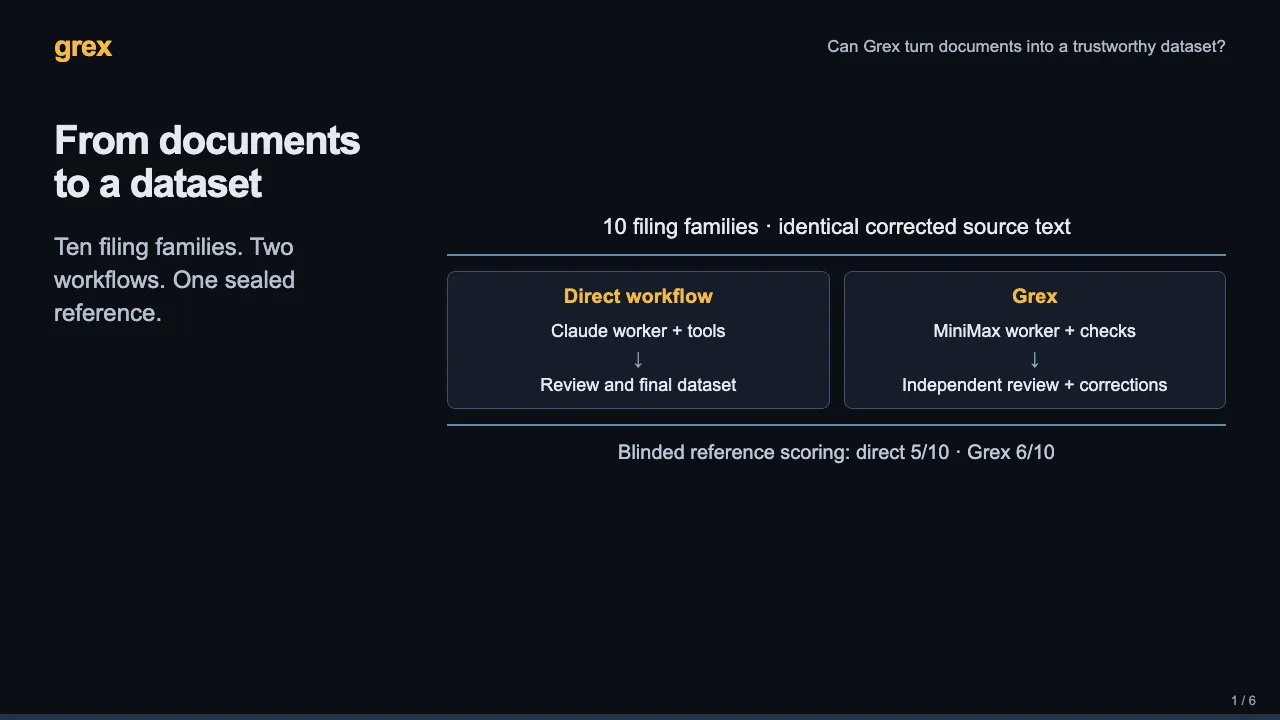
Can Grex turn documents into a trustworthy dataset?

Grex passed six of ten document families; the direct workflow passed five. Both matched the identity, date, number and name fields, with remaining acceptance failures concentrated in amendment interpretation. Grex used about 121 aggregate worker minutes versus about 16 for the baseline. This small, model-confounded comparison supports a near-tie, not superiority.

Grex 2.0 · October–November 2026

Completed · bounded comparison

Read the experiment · Watch the explanation

Website growth · Single-page before-and-after experiment

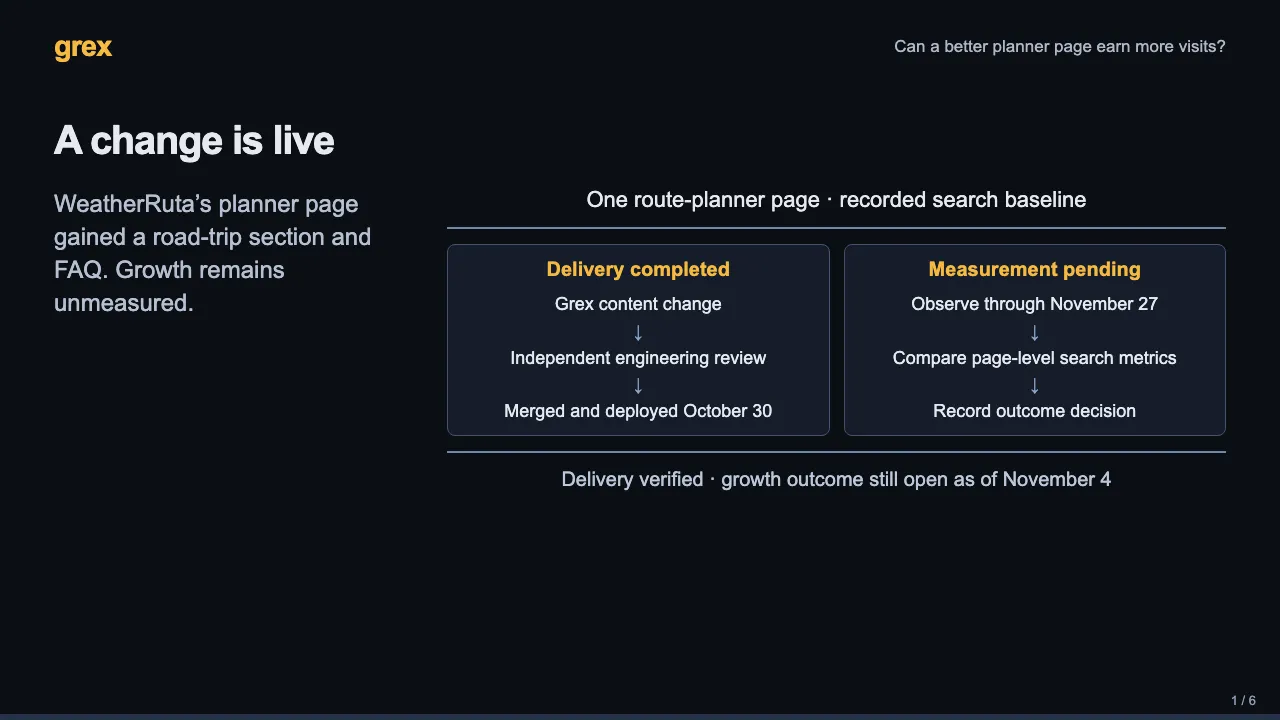
Can a better planner page earn more visits?

The content change shipped on October 30. As of November 4, the experiment has a recorded baseline but no outcome decision. Deployment is verified; search growth has not been established.

Grex 2.0 · October–November 2026

Observation open · decision scheduled for November 27, 2026

Read the experiment · Watch the explanation

Harness² · Bounded integration pilot

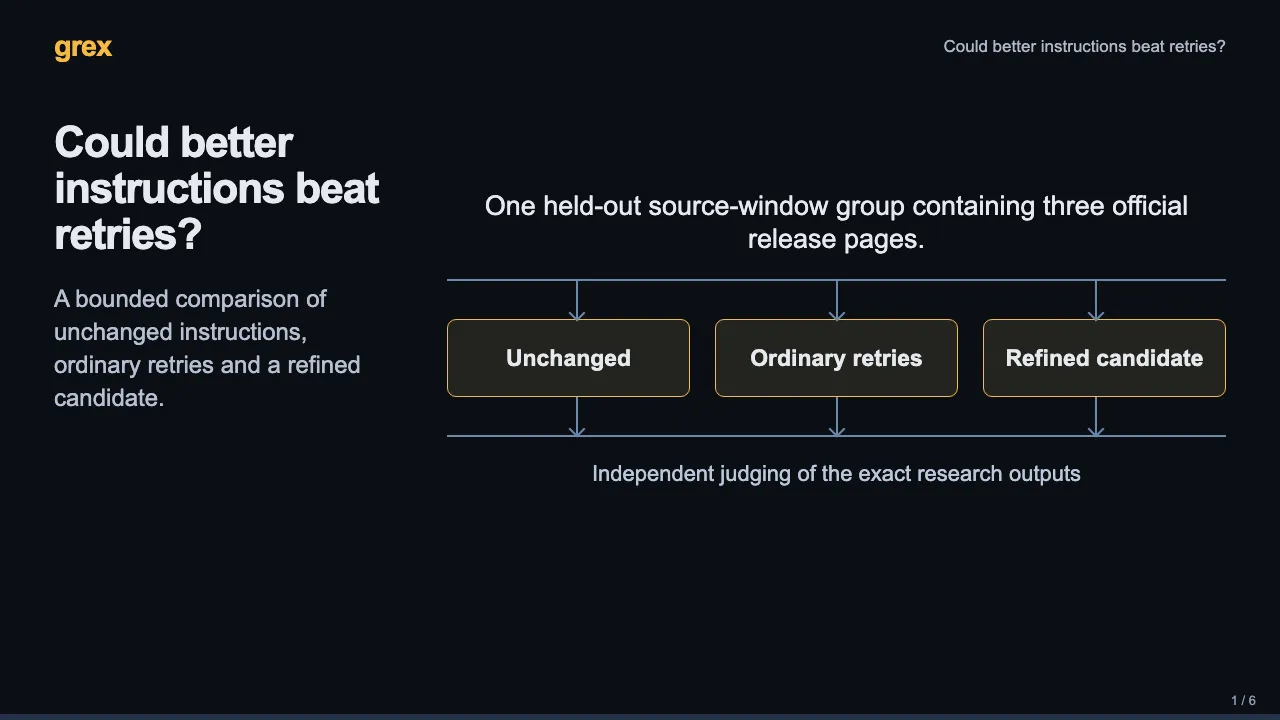
Could better instructions beat retries?

The unchanged instructions produced an accepted brief. Ordinary retries produced an accepted brief on attempt two. The frozen refined candidate passed mechanical checks but failed independent review with two unsupported claims. This was one source-window group, not a success-rate study.

Grex 2.0

Completed · adoption on hold

Read the experiment · Watch the explanation

Research briefs · Bounded reliability experiment

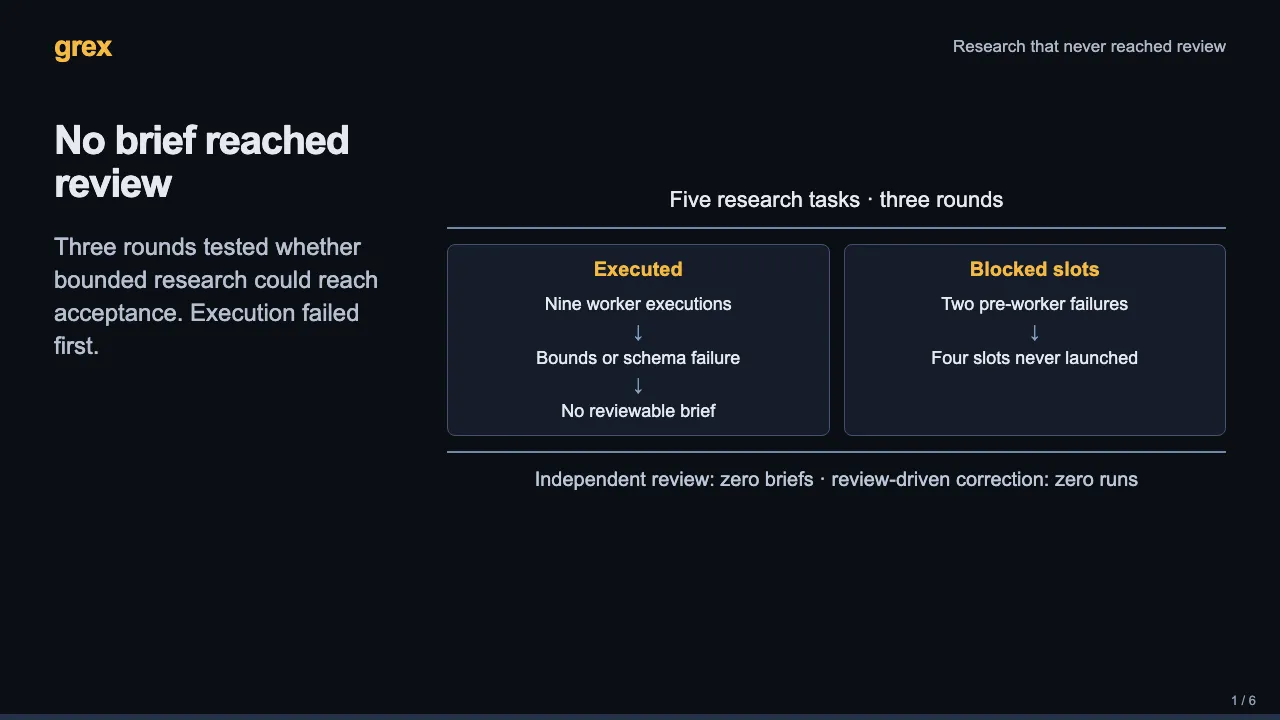
Research that never reached review

Across three rounds, nine worker executions produced no reviewable brief. Two further launches failed before worker execution, and four planned slots were not launched. No independent research review or correction ran.

Grex 2.0 · October 2026

Closed · quality target missed; no briefs reviewed

Read the experiment · Watch the explanation

Model roles and teams · Paired team comparison

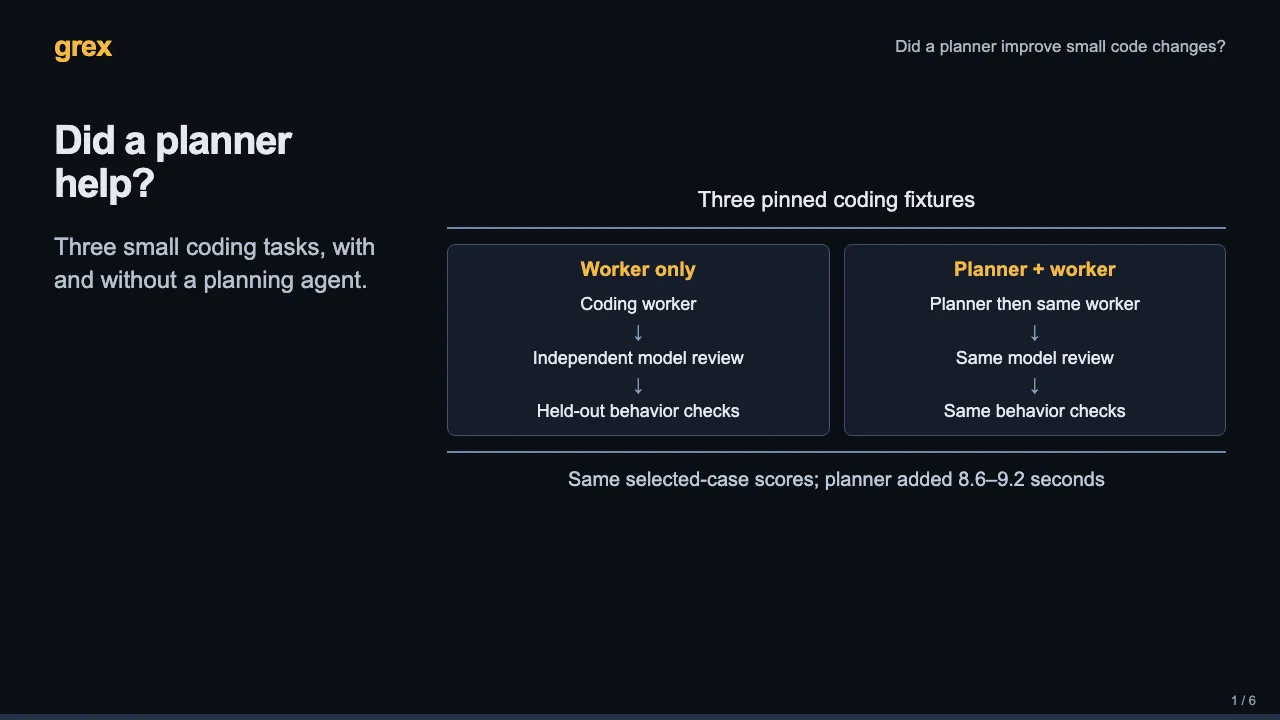
Did a planner improve small code changes?

Worker-only and planner-plus-worker submissions passed the same selected cases on all three tasks. Planning added about nine seconds per pair. All six model reviews accepted, but a separate source-level probe found an untested fallback bug in both diagnostic submissions. That task’s broader correctness remained uncertain.

Grex 2.0 · October 2026

Completed · diagnostic case uncertain

Read the experiment · Watch the explanation

Direct agents and orchestration · Paired execution comparison

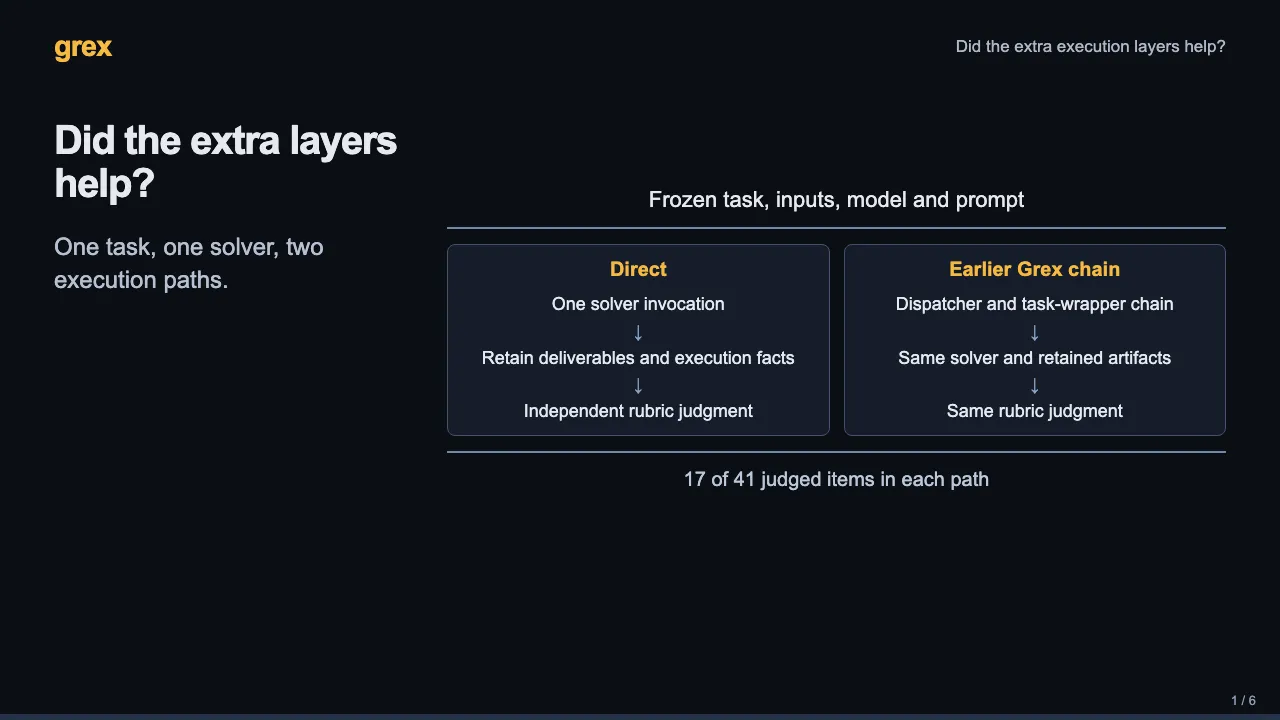
Did the extra execution layers help?

Across five pairs, direct execution and the earlier Grex chain each passed 17 of 41 judged rubric items. Individual pairs differed, and the judging had known limitations. The decision was to simplify single-task execution while keeping mission-level controls outside the experiment’s scope.

Historical Grex 1 · October 2026

Completed · historical architecture

Read the experiment · Watch the explanation

Early platform experiments · Benchmark attempts

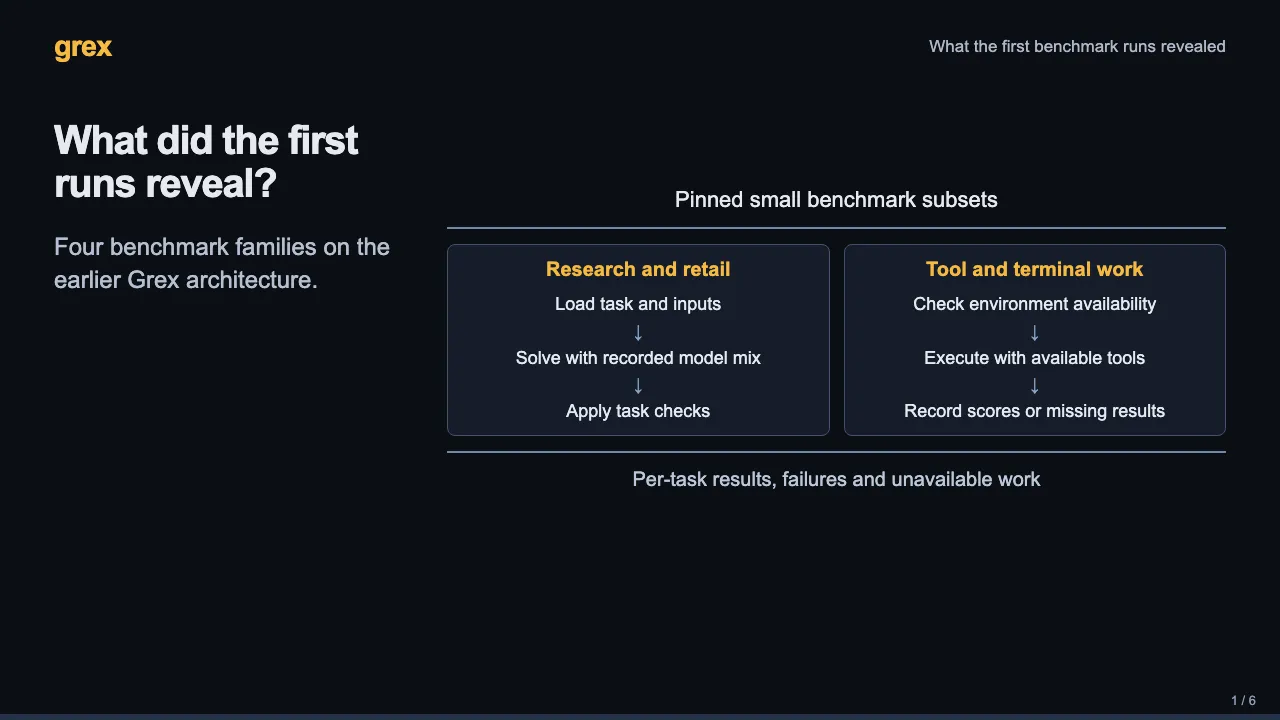
What the first benchmark runs revealed

The archived runs produced task results and several actionable failures. GAIA and retail-task samples completed more fully than some tool and terminal tasks. Different model mixes, harness revisions and samples prevent a platform-lift claim. These are historical attempts from the architecture that preceded Grex 2.

Historical Grex 1 · August 2026

Historical · mixed completion

Read the experiment · Watch the explanation

Discovery and growth experiments · Field calibration

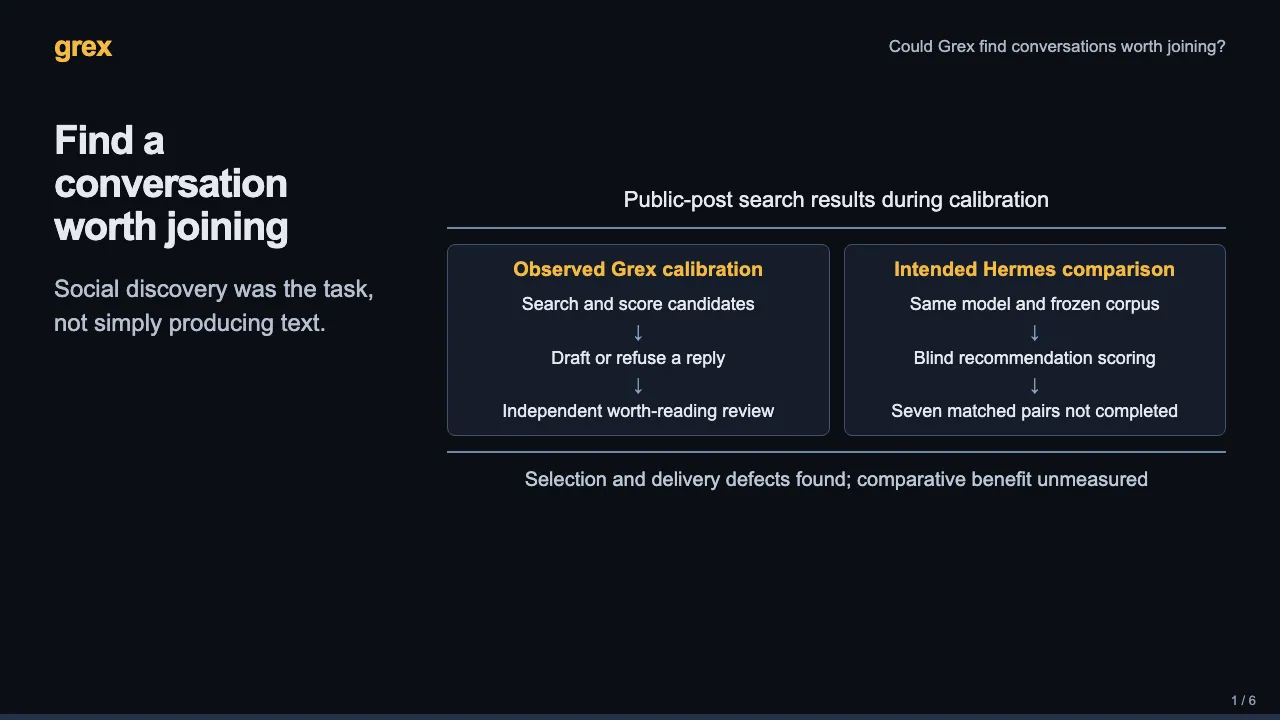
Could Grex find conversations worth joining?

The retained evidence covers Grex-side calibration, not the planned seven-pair comparison. Repeated searches rediscovered unsuitable posts, and one published internal brief contained refusal text as its suggested reply. A separate reviewer then judged that brief not worth reading. No Grex-versus-Hermes precision result was established.

Historical Grex 1 · August 2026

Calibration only · comparison held